Loading page

Analysis of 118K+ answers reveals dramatic differences in AI citation behavior: Perplexity averages 21.87 citations per question while ChatGPT uses 7.92, and OpenAI is the only model citing Wikipedia significantly at 4.8%.
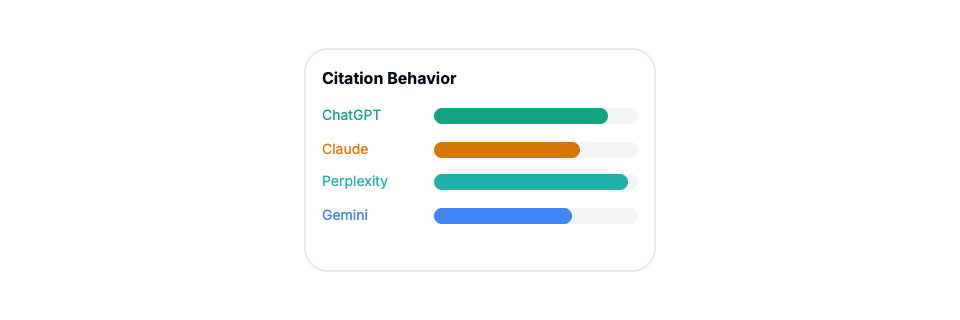
The biggest mistake in GEO: treating all AI providers the same. We analyzed 118,101 AI-generated answers with 669,065 citations across 8 major providers during Q3 2025. The data reveals dramatic differences in how each platform selects, cites, and positions sources.
What works for ChatGPT will fail for Perplexity. Wikipedia strategy succeeds on OpenAI, fails everywhere else. Platform-specific optimization isn't optional - it's essential. Our findings align with Princeton's GEO research showing platform-specific optimization is essential, and Search Engine Land's analysis confirming Wikipedia dominates ChatGPT citations. This report quantifies exactly how different these providers are, and what that means for your GEO strategy.
Here's how much each provider relies on external sources:
Provider | Cit/Question | Unique Sources | Diversity | Avg Position |
Perplexity | 21.87 | 37,399 | 79.8 | 5.66 |
Google AI Overview | 17.93 | 25,785 | 89.4 | 10.08 |
Gemini | 17.11 | 20,549 | 77.0 | 4.67 |
ChatGPT (OpenAI) | 7.92 | 42,592 | 83.4 | 2.82 |
Microsoft Copilot | 2.47 | 111 | 97.0 | 1.90 |
The spread is massive: Perplexity cites 2.76x more sources per question than ChatGPT (21.87 vs 7.92).
What this means: A brand that appears in 10% of Perplexity responses might appear in only 3.6% of ChatGPT responses - not because their content is worse, but because the platforms have fundamentally different citation strategies.
Citations per question: How many sources the AI model references per answer. Higher numbers indicate the model relies more heavily on external sources.
Unique sources: Total distinct domains cited during the quarter. Indicates breadth of source discovery.
Diversity score: Shannon entropy normalized to 0-100. Higher scores mean citations are distributed across many sources rather than concentrated on a few.
Average position: Mean placement of citations in responses. Lower numbers (early positioning) typically correlate with higher authority.
Here's where conventional GEO wisdom breaks down completely.
Wikipedia citation rates by provider:
Provider | Wikipedia Citations | Wikipedia Share | Other Sources |
OpenAI (ChatGPT) | 9,208 | 4.8% | 95.2% |
Microsoft Copilot | 0 | 0% | 100% |
Google AI Overview | 0 | 0% | 100% |
Google AI Mode | 0 | 0% | 100% |
Perplexity | 0 | 0% | 100% |
Gemini | 0 | 0% | 100% |
Anthropic | 0 | 0% | 100% |
xAI | 0 | 0% | 100% |
ChatGPT is 4.8% dependent on Wikipedia. Every other major provider: effectively 0%.
Why this is critical: The standard GEO advice - "get a Wikipedia page for AI visibility" - only works for one platform. If your target audience uses Perplexity, Gemini, or Google AI, Wikipedia presence provides minimal direct benefit.
Run a free audit: in a few minutes, ChatGPT, Gemini and Perplexity answer 8 buying questions about your market live, and you see who they recommend.
OpenAI's top cited sources:
Everyone else's top cited sources:
The pattern: OpenAI uses Wikipedia as a knowledge foundation, then cites specialized sources. Other providers skip the encyclopedia layer entirely and go straight to specialized content.
Strategic implication: If you're optimizing for ChatGPT specifically, Wikipedia presence is valuable. For multi-provider GEO, specialized vertical content is non-negotiable.
Profile:
What Perplexity prioritizes:
Why Perplexity cites so much: The platform's value proposition is comprehensive research. More citations = more thorough answers = differentiation from ChatGPT's concise responses.
Optimization strategy for Perplexity:
Success pattern: Leading legal platforms dominate Perplexity citations in the French legal vertical with comprehensive guides covering every aspect of business law formation, contracts, and compliance.
Profile:
What ChatGPT prioritizes:
Why ChatGPT cites less: The model is trained to provide concise answers drawing primarily from training data, using citations mainly for verification and recent information.
Optimization strategy for ChatGPT:
Success pattern: Brands with well-maintained Wikipedia pages + mainstream press coverage get cited significantly more in ChatGPT than in other providers.
Profile:
What Google AI Overview prioritizes:
Why diversity is so high: Google AI Overview appears designed to show multiple perspectives, resulting in highly distributed citations rather than relying on a few authoritative sources.
Optimization strategy for Google AI Overview:
Success pattern: Brands with strong YouTube presence + Google Business Profile + Maps reviews get cited more frequently in Google AI Overview.
Profile:
What Gemini prioritizes:
Why Gemini favors regional content: Unlike other providers, Gemini shows clear preference for local-language, region-specific authorities over global English content.
Optimization strategy for Gemini:
Success pattern: French business blogs and legal service providers dominate Gemini citations despite having minimal global brand recognition.
Profile:
What Microsoft Copilot prioritizes:
Why so few citations: Copilot integrates tightly with Microsoft 365 and appears to prioritize synthesized answers over extensive citation.
Optimization strategy for Microsoft Copilot:
Success pattern: Brands with coverage in Forbes, PCMag, TechCrunch get disproportionate citations despite Copilot's limited citation volume.
See which Reddit, YouTube, LinkedIn and forum discussions AI answers cite, where the model and country support it.
Priority tactics:
Lower priority:
5. Niche vertical content (ChatGPT prefers mainstream)
6. Regional/local optimization (English/global focus)
7. High citation volume tactics (only 7.92 avg)
Measurement: Track citation position (aim for 1-3) more than citation volume.
Priority tactics:
Lower priority:
5. Wikipedia (0% share)
6. Mainstream press (not in top sources)
7. Early positioning obsession (mid-response is normal)
Measurement: Track citation volume (aim for multiple citations per response).
Priority tactics:
Lower priority:
5. Dominant citation share (diversity = multiple sources cited)
6. Early positioning (late citations normal)
7. Non-Google platforms
Measurement: Track citation frequency across Google ecosystem.
Priority tactics:
Lower priority:
5. English-only content
6. Global positioning
7. Wikipedia (0% share)
Measurement: Track regional citation share vs. global competitors.
Most brands need visibility across multiple providers. Here's what works everywhere:
Universal tactics:
Provider-specific additions:
The wrong approach: Optimizing exclusively for one provider. Even if 70% of your audience uses ChatGPT, ignoring the 30% on Perplexity means missing significant opportunity.
The data is unambiguous:
The mistake most brands make: Following generic "GEO best practices" that assume all AI providers behave identically.
The winning approach: Platform-specific optimization based on where your audience actually uses AI, measured with provider-specific metrics. If you're not tracking performance by provider, you're flying blind.
This is part of our Q3 2025 research series on AI citation behavior.
Overview Studies:
Deep Dive Reports:
Want provider-specific tracking? Qwairy monitors your brand across all major AI providers with platform-specific metrics and insights.
External validation: Our findings are corroborated by multiple 2025 industry studies:
Research powered by Qwairy - Track your brand's performance across ChatGPT, Perplexity, Gemini, and 7 other AI platforms.
Track the questions that matter to your business, see which brands each answer mentions and which sources it cites, then work on the gaps.
Free plan with 120 initial credits • No credit card required
Other Articles
The First Answer Isn't the Decision: How AI Assistants Keep Buyers Talking
AI assistants rarely end on an answer: 72% close by inviting another question. And once buyers answer, the shortlist reshuffles. Qwairy's benchmark shows what the next turn decides.
After the Sale, AI Sends Customers Back to Your Website. Until Something Breaks
After a purchase, 90% of AI answers cite the brand's own website, versus 17% before. But troubleshooting is the weak spot. Qwairy's benchmark maps who AI cites at every step after the sale.